The allowance is real, but the unit is hard to see
An AI subscription can show plenty of allowance in the morning and stop a paid workflow that afternoon. The immediate suspicion is a silent quota cut. The documented reality is less dramatic but commercially important: major AI services increasingly sell access to a variable compute budget, while presenting that budget through percentages, sessions, weekly pools and reset dates that users may reasonably mistake for fixed message counts.
Recent complaints span ChatGPT, Claude, Gemini and Grok. They do not prove that four providers secretly reduced limits. The reports are self-selected, lack provider-side logs and mix plan tiers, models, context lengths, tools, regions and rollout cohorts. Yet they expose the same practical problem: customers often cannot predict what a request will cost, when capacity will return, or whether pressing “reset” adds allowance or starts a new billing-like clock.
That distinction matters as subscriptions become compute meters rather than simple access passes. It also separates this issue from post-launch reports about GPT-6 Astra speed and quality. Here, the central question is accounting transparency.
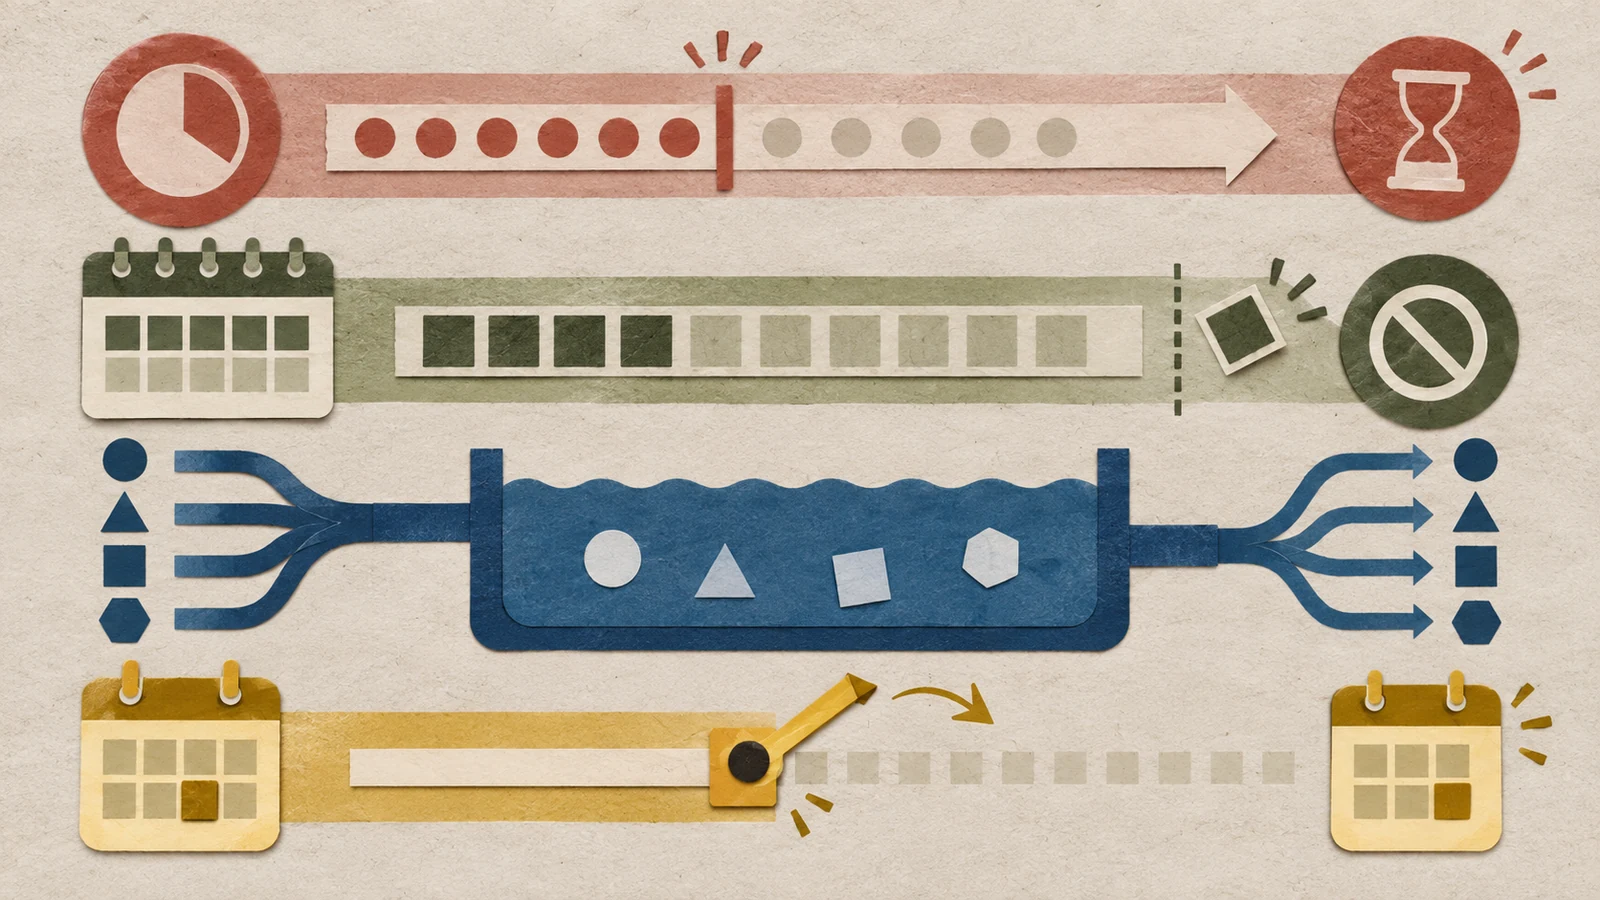
Four services, four versions of “usage”
| Service | Official accounting | User-facing friction reported |
|---|---|---|
| ChatGPT | Weekly Work/Codex periods; an instant reset advances the allowance and starts a new period after the next request. | Reset dates moving later; temporary meter swings. |
| Claude | Five-hour sessions plus fixed weekly limits; usage varies by model, effort, features and context. Products share limits. | Unexpected plan exhaustion and separate-credit spending. |
| Gemini | Compute-based limits refresh every five hours until a weekly limit; capacity can change. | Large percentage drops after apparently modest prompts. |
| Grok | One weekly pool spans Chat, Imagine, Voice and Build; products consume different compute amounts. | Cross-product depletion and changing displayed reset dates. |
The table also shows why the same word—“limit”—can conceal different customer experiences. A session window controls near-term access; a weekly ceiling governs the longer horizon; a shared pool lets image, voice or coding activity reduce what remains for chat; and paid credits can continue work while creating a separate bill. Those mechanisms are not interchangeable, even when each appears as one declining percentage.
Reset language is especially consequential. A customer may read “reset” as restoration of the original schedule plus extra capacity. OpenAI’s rule instead treats it as the beginning of a fresh period, anchored by the next eligible request. Similarly, a provider can accurately show that a pool refreshes every five hours while a weekly ceiling prevents meaningful recovery. A technically correct label can therefore produce an economically wrong expectation.
No public evidence in this sample establishes that the meters calculate incorrectly across the board. The useful comparison is whether the interface reveals enough inputs for a subscriber to anticipate the result. On that measure, raw percentage remaining is thin disclosure: it shows an outcome without showing the compute-weighted path that produced it.
ChatGPT: a reset can move the calendar
OpenAI provides the clearest corroborated example. On September 9, its status page recorded and resolved an incident involving unexpected usage-limit resets. Separately, users described dashboard behavior that looked inconsistent: one weekly allowance reportedly fell from 81% remaining to exhausted, then returned. That is evidence of a displayed-state anomaly experience, not proof that usage was permanently removed.
Other complaints are better explained by the rule itself. A September 16 user said using a purchased or banked reset moved the next renewal from September 19 to September 23. Another said a free reset moved a September 6 renewal to September 11. OpenAI’s official reset guidance says an instant reset applies immediately, starts a new weekly period after the next Work or Codex request, and puts the next automatic reset seven days later. It advances normal allowance; it is not a second bucket layered on top.
Claude: shared limits and separate credits
Anthropic’s rules combine more dimensions. Its usage-limit documentation says consumption depends on conversation length, complexity, model, features and effort. Claude.ai, Claude Code and Claude Desktop share limits, while Max plans have five-hour session limits and a fixed weekly ceiling. Recent Fable rules add another boundary: Max users may spend up to 50% of weekly allowance on Fable models, while Pro users use pay-as-you-go credits.
One Max 20x user reported unexpectedly reaching the plan limit and consuming about $100 in usage credits within roughly 30 minutes; another commenter described a similar event after using only 15% of Fable. This is an attributed experience, not evidence of a billing defect. Anthropic says usage credits are billed separately at standard API rates. Separate reports about promotional balances disappearing before a displayed expiry should also not be conflated with purchased-credit rules. Anthropic’s status page showed no usage-limit incident through September 20, although it listed unrelated Fable and Mythos errors.
Gemini: “simple” prompts can carry hidden weight
Gemini users reported a simple Flash 3.7 question consuming 6% of a five-hour allowance, a few questions and screenshots exhausting another allowance, and engineering-study sessions reaching the limit twice within two hours. Others said four fan-fiction chapters exhausted a paid limit. But a September 17 claim that Antigravity quota had been halved drew direct contradictions from commenters whose quotas appeared unchanged.
Google’s official explanation is that Gemini limits are compute-based: prompt complexity, model and feature choice, and chat length all matter. Limits refresh every five hours until a weekly ceiling, and may change with capacity. That can explain variable percentage costs without establishing a silent reduction. Google Cloud reported no broad severe incident on September 20.
Grok: one pool, several expensive products
xAI makes the cross-product tradeoff explicit. Its Grok FAQ says paid users draw from one weekly pool across Chat, Imagine, Voice and Build, with different products consuming different amounts based on compute. Extra Usage Credits arrive immediately, generally expire after one year, and cost more per action than included usage.
Users nevertheless described surprising depletion. One said three 15-second videos consumed 10% of weekly usage, versus roughly eight videos for the same displayed percentage the prior week; another reported two short videos consuming 10%. The arithmetic is striking, but the comparison is not controlled: clip parameters are unknown and percentages may be rounded. Another subscriber said a reset date changed from August 29 to September 3 after subscribing and exhausting usage. xAI declared no corresponding status incident.
Transparency is now part of the product
The strongest conclusion is not fraud, conspiracy or universal quota reduction. Official rules support compute-weighted variation, and the anecdotes have no representative denominator. A short prompt can carry long context or tool activity; percentages can be rounded; and identical-looking requests may use different models or effort settings.
But intended metering can still be poorly communicated. Providers could show the active window, the next reset consequence before confirmation, the products sharing a pool, and a request-level cost explanation. They could also separate included allowance, promotional balance and paid top-ups visually. When capacity rules may change, a dated change log would help customers distinguish policy from malfunction.
For subscribers, the practical reading is narrower: a reset may move the next reset date rather than add capacity, and a percentage is not a message counter. For providers, that ambiguity is no longer a minor interface issue. Once extra usage is sold after exhaustion, meter clarity becomes part of the commercial promise.
Image disclosure: The featured image and inline comparison diagram are original AI-generated editorial visuals. They do not reproduce any provider interface or represent benchmark data.