AWS announced general availability of SageMaker AI training sessions on October 22, 2026, offering teams a way to customize models while AWS manages GPU allocation, distributed execution, fault recovery, and checkpoint storage. The launch announcement describes infrastructure management moving to AWS while users retain control over custom losses and reward signals.
For teams considering supervised fine-tuning or reinforcement learning, the practical question is how much work remains. The documented boundary leaves substantial responsibility with the team designing the experiment.
A loaded model, an ongoing conversation
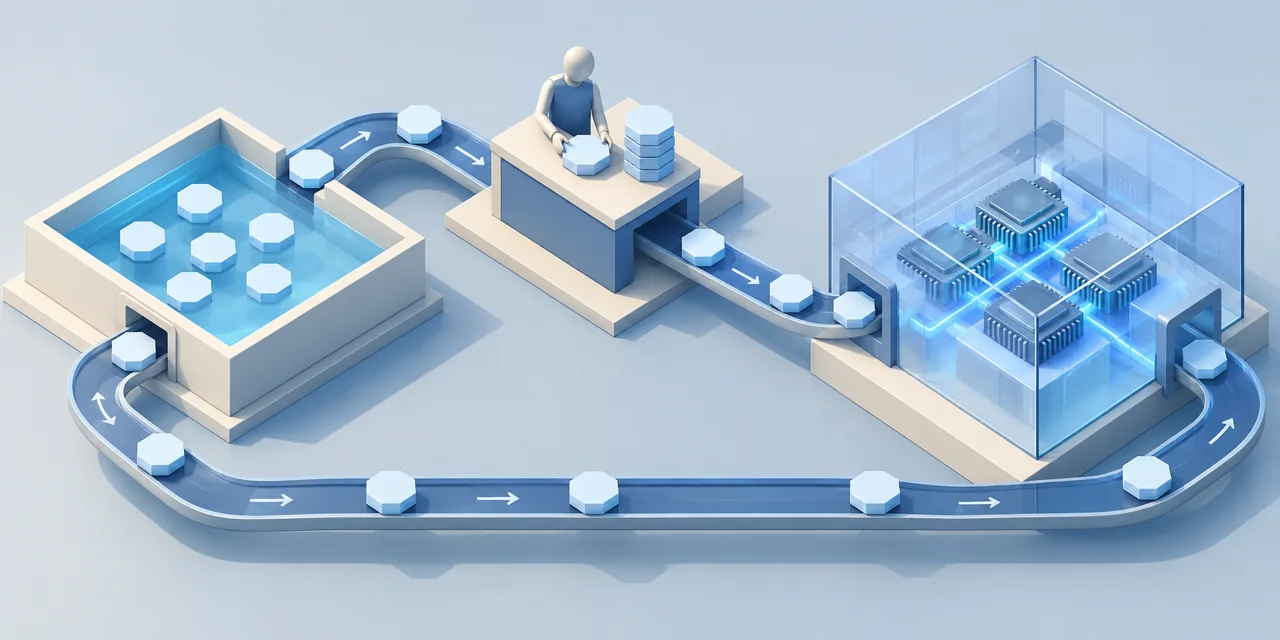
In AWS’s technical walkthrough, a Python process controls a live session, and the model stays loaded on managed GPUs between calls. Teams supply data, environments, rewards, and loop control; the service performs GPU operations.
The API documentation describes individual calls such as sample, forward_backward, and optim_step. That gives developers control over the sequence of training operations instead of requiring one submitted training script. Editorially, the distinction matters: changing the procedure remains part of the developer’s job.
The experiment still belongs to the team
The AWS cookbook provides supervised fine-tuning, math and competitive-programming reinforcement learning, and preference-optimization recipes. Its setup requires a model reference, execution role, model package group, and S3 output path in the selected Region.
The repository also describes evaluation, checkpointing, and metrics, with run folders recording configuration, a Git hash, metrics, and checkpoint references. Those records offer a useful starting point for reproducibility. Teams attempting a reproduction should pin the code version and record the account, model, and Region rather than assume a changing main branch preserves an experiment.
Billing and recovery need separate scrutiny
The API page identifies three charging dimensions: prefill, sample, and train. AWS’s walkthrough says token-based billing pauses while a local reward function scores a batch. That may matter for loops with substantial scoring work, but the reviewed material does not supply enough rate detail to estimate total cost or establish savings.
Recovery also deserves explicit planning. The core operations guide distinguishes inference-ready weights from resumable training state. Restoring optimizer state requires the corresponding operation; restoring weights alone starts a fresh optimizer. A saved model therefore does not automatically mean an experiment can continue with its previous optimizer state.
A demonstration with a narrow conclusion
AWS reports that its GPT-OSS 20B example used a LoRA adapter and GRPO on 40 math problems, with held-out accuracy rising from 56% to 75% after 10 steps. The technical walkthrough demonstrates a workflow; its result does not establish production accuracy or general performance.
All five reviewed sources are vendor-authored. This report includes no hands-on API test, account inspection, or independent reproduction. The appropriate adoption question is whether the workflow succeeds on a team’s representative evaluation, with costs and recovery behavior measured alongside model quality.
Check availability before committing
As checked October 27, the launch announcement lists Qwen3.8-27B alongside GPT-OSS-20B, Gemma-4-31B-it, and Qwen3.6-27B. The API page lists only the latter three and says availability varies by Region. That discrepancy warrants checking the desired model and Region; it does not establish that the omitted model is unavailable. The documented default quota is two concurrent fine-tuning sessions, adjustable by request.
For related infrastructure context, our coverage of NVIDIA’s Mamba-2 kernel benchmark concerns a narrower performance question. Here, the decision centers on control of the training procedure and the responsibilities that managed infrastructure leaves with its users.
Sources
- AWS launch announcement — October 22, 2026.
- AWS training-loop walkthrough — October 22, 2026.
- Training session APIs — undated; checked October 27, 2026 KST.
- Core operations — undated; checked October 27, 2026 KST.
- AWS training sessions cookbook — mutable repository; checked October 27, 2026 KST.